
ElevenLabs v4
- Length
- 17.8 s
- Whisper starts
- 3.95 s
- Returned in our run
- about 11 s
- This script
- 9 credits
- Per 1,000 characters
- ≈ 28 credits
Final reads, trailers, narration that has to carry a scene.
ElevenLabs v4 turns up to 5,000 characters into expressive speech. Direct it with audio tags, fix names with IPA, and draft cheaply in Turbo.
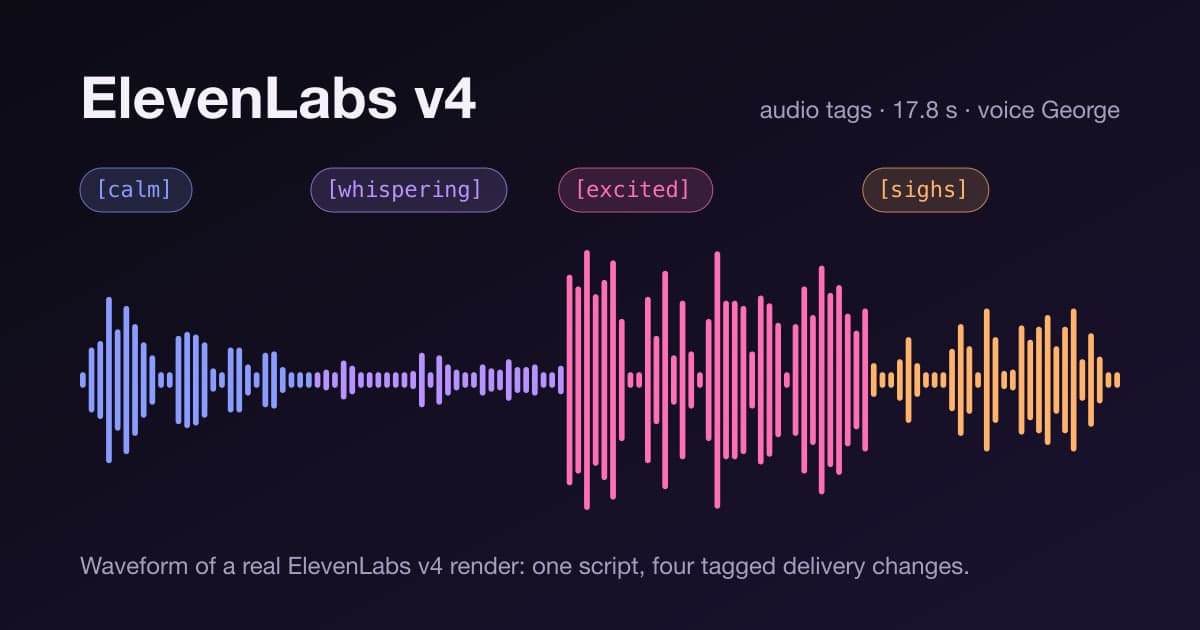
Real render · voice George · 17.8 seconds · 9 credits
One ElevenLabs v4 generation, not four stitched clips. The score shows where each bracketed tag took over in the actual file.
[calm]0:00–0:04At five in the morning the harbor is almost silent.
Even level, unhurried phrasing.
[whispering]0:04–0:08Listen closely... the first engine is already turning over.
The quietest stretch, consonants still clear.
[excited]0:08–0:13And there it goes: the whole fleet, one boat after another, heading for open water!
The loudest five seconds.
[sighs]0:13–0:18Somebody still has to stay behind and mend the nets.
A breath, not the word.
[calm] At five in the morning the harbor is almost silent. [whispering] Listen closely... the first engine is already turning over. [excited] And there it goes: the whole fleet, one boat after another, heading for open water! [sighs] Somebody still has to stay behind and mend the nets.
Same script, same voice, two tiers
Identical script and settings on both tiers: the whisper starts at almost the same moment and the lengths differ by a tenth of a second, so Turbo is a faithful preview of pacing. Whether the quality tier is worth twice the credits is a listening call.
Final reads, trailers, narration that has to carry a scene.
Drafts, retakes, long lists of short lines.
Names, numbers and IPA
A name the voice has never seen and a date in digits: this reminder handles both.
13.2 s · 241 characters · 7 credits
[friendly] Hi, this is a reminder from Riverside Dental. Your appointment with Doctor /ˈiːfə/1 Brennan is confirmed for Tuesday, March 3rd at 2:30 PM2. [reassuring] If you need to reschedule, just reply to this message. It only takes a minute.
Voices and languages
Preset voices, none cloned from a real person. Each card lists the exact settings, so you can rerun it and change one thing.
[cheerful] ¡Buenos días a todos! Bienvenidos al mercado del sábado. Hoy tenemos pan recién horneado, tomates del huerto y, como siempre, café caliente para los que madrugan. [laughs] Y sí, también hay churros.
Good morning, everyone! Welcome to the Saturday market. Fresh bread, garden tomatoes and hot coffee for early risers. And yes, there are churros too.
[softly] 今夜は雨の音を聞きながら、ゆっくり目を閉じてみましょう。[whispering] 明日のことは、明日の自分にまかせて。おやすみなさい。
Tonight, listen to the rain and slowly close your eyes. Leave tomorrow to tomorrow's you. Good night.
[gruff] You want the mountain pass? [laughs] Nobody has crossed it since the snow came early. [serious] Take the lantern, keep left at the broken bridge, and do not, I mean it, do not stop to rest.
Credits count characters, so a Japanese or Chinese script costs the same per character as an English one.
Credits scale with characters
Every character counts, tags included. Spoken length assumes the pace of our English samples, about sixteen characters per second. New accounts start with 50 free welcome credits.
Generator settings
Lower lets tags swing harder; higher keeps a long read even. The game line used 0.4.
How tightly the read holds the preset timbre. Very high can sound less natural.
21 presets · default RachelGeorge, Sarah, Laura, Lily and Brian are the voices heard on this page.
empty = detectSet es, ja and so on for short or mixed-language lines.
auto · on · offOn spells out dates, prices and times; off keeps codes and serials literal.
optionalBest-effort repeatability, not a guarantee.
The shaded band is where our takes sounded natural; the marker is the default.
Writing for the model
Put the tag directly before the words it should color.
[whispering] Listen closely...Give each sentence one mood. Two stacked emotions force a compromise.
[excited] And there it goes!Let punctuation carry timing: ellipses and dashes pause, exclamation marks lift.
do not, I mean it, do not stopSound tags become sounds, not words. Check one take, then reuse the pattern.
[sighs] Somebody still has to stay behindReplace a hard name with its IPA in slashes. Never write both.
Doctor /ˈiːfə/ BrennanDraft in ElevenLabs v4 Turbo, then regenerate the approved script in ElevenLabs v4.
same text · same voice · same seedChoosing a voice model
Tag-directed performance and IPA. The default here.
The same controls at half the credits for drafts and volume.
Keep ElevenLabs v3 for a series already voiced with it.
Multilingual v2 and the fast v2.5 models remain available from the ElevenLabs voice generator.
For a conversation, Gemini TTS voices two speakers in one file.
Compare all of them on the text to speech page.
ElevenLabs v4 is the fourth-generation text to speech model from ElevenLabs. It reads up to 5,000 characters per request in a preset voice and follows inline audio tags such as [whispering], [excited] or [sighs].
Write the tag in square brackets directly before the words it should color, for example "[whispering] Listen closely...". The tag itself is not spoken. Sound tags such as [laughs] or [sighs] become a vocal sound. Keep one mood per sentence.
Both take the same text, tags, voices and settings. ElevenLabs v4 Turbo costs half as many credits and returned faster in our tests; ElevenLabs v4 is the quality tier for final reads.
Credits scale with script length: about 28 credits per 1,000 characters on ElevenLabs v4 and about 14 on ElevenLabs v4 Turbo. A 100-character tagline costs 3 credits on ElevenLabs v4; a full 5,000-character request costs about 140. New accounts receive free welcome credits for testing.
ElevenLabs v4 is multilingual. On this page we generated English, Spanish and Japanese with the same model. Leave the language code empty to detect it from the text, or set a code such as es or ja for short lines and mixed-language scripts.
Replace the word with its IPA pronunciation between forward slashes, for example "Doctor /ˈiːfə/ Brennan". Do not write the name and the IPA together: in our first test that made the voice say the name twice. For dates, prices and times, turn text normalization on.
Each request accepts up to 5,000 characters, which is roughly five minutes of English speech at the pace of our samples. Split longer scripts into scenes with fixed voice and settings.
Not on this page. ElevenLabs v4 on Voor uses 21 preset voices such as Rachel, George, Sarah and Brian. Never use synthetic speech to impersonate someone without consent.
Start new projects on ElevenLabs v4 when you need tag-directed delivery, IPA pronunciation or the cheaper Turbo tier. Keep ElevenLabs v3 for a series that is already voiced with it.
Write one line, tag one mood, and listen. Draft in Turbo, then keep the read that sounds like your scene.
Generate with ElevenLabs v4Optional cookies help us understand usage and measure ads. Essential cookies stay on so Voor works.